Both books were published on March 10, and both authors are talented, with impressive bylines, with significant followings baked in. Incidentally, they come from the same cohort we loosely refer to as “feminist blogging,” though both would probably bristle at the description. And both use autoethnographic methods to leverage their personal lives to tell bigger stories about social, cultural and economic dynamics (a common method among feminists, where the personal is often made explicitly political). Lemieux goes further by including a series of essays by other Black single mothers at the end of her book, expanding the frame from memoir into something more collective, a full bloom.
West’s book has gone ultra viral over the last few weeks while Lemieux’s has found significantly less footing. West’s work is being spectacularized in real time, while Lemieux’s support has been mostly grassroots, respectful (thankfully), and largely limited to Black media outlets and NPR. This reproduces one of the oldest patterns in feminist media: a white woman’s confessional work circulates as universal or spectacular (West is being treated like a spectacle currently, which is great for sales and visibility but comes with negative trade-offs), while a Black woman doing rigorous, arguably more structurally ambitious work gets categorized as niche, an outlier. That this is happening within the very audience that would generally name and critique this dynamic in any other context makes it worth sitting with.
While I respect both authors and their bodies of work, I am looking forward to Lemieux’s book because I know firsthand how difficult it is to get a publisher and an audience for serious, foundational work like this. I suspect it will prove relevant long after the viral moment is over.
Rapper Afroman is going ultra viral this week as his “Lemon Pound Cake” trial plays out in the news. He captured the raid on security cameras in his home and used the footage in a series of songs, videos and merch. He ultimately did not face charges after the search, and argues (with evidence) that the police broke his door and stole $400, which provides the platform and substance for everything that followed. He argues the police shouldn’t have been there at all, and didn’t follow protocol when they were, and that as a citizen and artist he’s expressing his feelings about it in his preferred medium. Is this a winning legal strategy? Time will tell.
In the meantime he’s winning at public opinion. The trial is shaping up in the public view as a defamation vs. free speech trial, with the artist’s prolific work about this no-knock raid performed at his house, itself arguably unethical, held up as harassment by the officers who did the job. True crime, legal experts and court watcher accounts are going gangbusters providing cultural and legal analysis alongside video of court testimony. It helps that the court footage is a rich text — both hilarious and revealing.
My digital presence has been deliberately fractured for years, so I’m watching how this site stitches together my breadcrumbs through SEO, with the serious stuff and throwaway asides alongside the occasional hilarity. Currently one of my top Google results.
NYT on the trend of “Luddite teens.” I have a growing suspicion that various neo-Luddist trends will largely map to class identity. In some areas of the world, in some areas of the US, Facebook is the internet, yellow pages and water cooler, and the internet experience is entirely mediated by apps.
Doing numbers on Twitter/X this week: this paper tested 70+ LLMs on open-ended prompts and found they all produce strikingly similar outputs. Worse, the systems used to improve models actively penalize diversity, reinforcing the convergence.
One of the more useful things you can do with an LLM is hold up a few ideas side by side and apply lenses to them. I know this history pretty well, so I asked a series of LLMs, why is Wisconsin’s cultural identity and cohesion stronger than Indiana’s, from a historical and business perspective?
Each LLM will give us more or less the same story, different flavor. Within the industry, the differences across the models reflect “model personality.” Asking “why” instead of “whether” will probably drive the answer to favor Wisconsin. Using multiple lenses (two states, historical + business, identity + cohesion) forces the LLM to cross-reference across more of its training data, which tends to produce a more comprehensive answer.
Functionally: all of them acknowledge hard historical truths within the subject matter and don’t shy away from critical perspectives, which is good. Both Gemini and Copilot include in-line links, which lets you judge the output’s authority in the moment as a reader. I liked Copilot’s more than I expected here. Claude’s answers are more lyrical and do provide more context, and yet do not encourage checking against outside sources by providing links within the output. And you can see that even with the good writing skill calling out hard bans on certain structure, Claude plows right through them.
Model personality: Claude favors sociological answers to Copilot’s economic answers. Claude is also highly intellectual and narrative by comparison, and that narrative style can mask nuance by sinking relative context within the storytelling. Gemini simplifies, boosts and cheerleads where the others don’t, and really goes hard on Wisconsin’s reputation as a drinking and Packers state when there are stronger structural arguments in play. Copilot is tricky because it looks authoritative like a briefing, which also makes it easily “extractible” for the user, but every citation requires authentication unless this is one of those “good enough” tasks.
As a writer, something I find annoying across the whole spread is the semantic reveal. LLMs are semantic machines, and it is persistently revealed in ways that are weird to the human ear. All of them go out of their way to describe things as “structural,” “connective” as in “connective tissue,” “load-bearing” and “legible.”
Finally, I included a second tab where I asked Claude for analysis across the four outputs, where it suggests that my framing of the question is altogether kind of problematic. It shows how a strong prompt is sometimes also a bad approach.
There are a lot of possible takeaways here, but I’d rather set aside the question of which tool is “good” or “bad” or “better” and think more about the patterns across the tools and their implications.
One of the tricky things about consumer AI tools like Claude and Gemini is that the experience varies widely depending on the person using it, and it’s not always clear why. I have spent a lot of time learning the tools so I can advise on them in my work, and this variance of experience has become a frustrating part of the deal.
I manage a team of writers and creatives at work, and we are expected to be familiar with the tools, despite complex and sometimes hostile feelings about the political and environmental implications of this sector. That’s quite a pickle, organizationally, managerially. Borrowing from Haraway, I thought, okay, what if we take these tools seriously as a team of writers and creatives and put our professional standards up against them?
Among other exercises, I did a couple of comparisons on my team that help create discussion around the “plausibility” question. People dismiss LLM outputs as being merely plausible answers, rather than accurate or factual ones. And that’s correct; they are, and that’s the design. In many cases, plausibility is fine. Take Wikipedia, for example, which we understand to be a pretty good source, a plausible source, unless you’re writing a formal paper requiring original sources.
I digress. Ultimately, we needed to understand together that LLMs are not a WYSIWYG tool and talk through the implications.
I asked everyone to run the same paper through their LLM of choice, prompting it for a plain language summary. We then copied and pasted it into a shared doc, and compared and contrasted for discussion. Upon discussion, we had several takeaways, including that they were all similar in spirit but sometimes varying wildly in style and approach.
Knowing that algorithms are responsive and not static, we did it again later in the day and copied and pasted our outputs into the shared doc. We compared and contrasted the difference between AM and PM. Again, it was similar in spirit but varied in style and approach. Some changed dramatically. One team member whose morning summary had been jokey and conversational received a much more staid and serious version in the afternoon.
At the time, I asked Claude to explain the variance: “Even with the same prompt and source material, LLMs don’t produce identical outputs each time. This is by design — there’s a degree of randomness (called “temperature”) in how the model selects words, which means each run produces a slightly different path through the text.”
Anyway, this got our gears turning on how (and whether) to approach LLMs as a team and as individuals and led to good group discussion. (It’s important to create space for criticism and critical approaches here.) It also gave us more confidence as a team responding to this new layer of complexity in our work, and helping our professional contacts and peers think about how to approach the tools and when and whether to use them. There will be tasks where AI-based tools are “good enough,” and tasks where they are not.
The swirl of mystery and speculation around this sector has people up in arms, and it’s useful to have approaches that give people firsthand experience and to see how the experience works for others. The god trick of the singular interface turns out to be a bear for navigating it in the workplace, where our work is foundational, prosocial and specific.
A note on Ezra Klein: I’ve been looking across the NYT’s breathless reporting on the AI industry and seeing very few women represented across the commentary. Klein’s tech coverage tends to center a fairly narrow circuit of sources: founders, researchers, and policy thinkers who are overwhelmingly male and concentrated in a few institutions, and generally assert the inevitability of disruptive AI as a matter of course. Meanwhile, Anthropic and others are anticipating that career ladders where women are concentrated will be impacted, some claiming professional women’s jobs will dry up or disappear entirely.
I looked over his podcast guests for the last year and noticed that among his tech-focused guests, almost all white, almost all men, almost none of them are women. A rough count of eight podcasts (nine if you stretch) with accompanying commentary only produced two women, both economists. Klein’s brand is the guy who does the reading, the big ideas guy. So it’s worth asking what he’s reading and whose ideas he considers big. While he probably wouldn’t disagree with Gebru or Crawford or Noble on the substance, his current body of commentary is pulled toward the perspectives of people who have the most to gain from the technology’s expansion and the least exposure to its costs.
She draws on Acemoglu and Restrepo’s concept of “so-so” technologies and traces a pattern from MOOCs to DOGE, where each iteration promises transformation but delivers incremental improvements at best and labor displacement at worst. The real danger, she argues, is that AI’s most compelling use case in the current political environment is threatening, demoralizing workers and justifying cuts, not revolutionizing how work gets done.
Cottom has been one of the writers I keep returning to because she is not dismissing the technology or retreating into reactionary nostalgia. She looks past the product announcements to the political economy underneath them. Who benefits from the hype cycle? What happens to the institutional infrastructure (education, research, public expertise) that AI claims to augment and simultaneously threatens to starve? She’s also very active on Instagram (and promoting a new documentary) and tracing the news around AI and higher ed in real time.
LLMs have a default house writing style with identifiable patterns: sentence fragments for emphasis, “not X, but Y” constructions, lots of hard contrast, atmospheric openings, heavy use of em dashes, and heavy use of marketing language. This reflects the semantic construction of an LLM. Custom instructions can override these defaults. A custom skill is a set of instructions within your account that modify how the model generates text. When you paste instructions into your profile settings, Claude reads them at the start of every conversation and adjusts its output accordingly.
I began using Claude daily for light writing tasks about six months ago, and over that time I started cataloging the patterns I was consistently editing out, including the terrible “not X, but Y” construction that showed up in nearly every response, and persistent em dashes used as all-purpose connectors when other punctuation is more appropriate.
I went through several iterations of bullying Claude into submission, narrowing the scope each time, before arriving at this version, which focuses specifically on writing mechanics and hard prohibitions.
You’ll need a paid Claude plan (Pro, Max, Team, or Enterprise). Free-tier accounts don’t have access to custom skills.
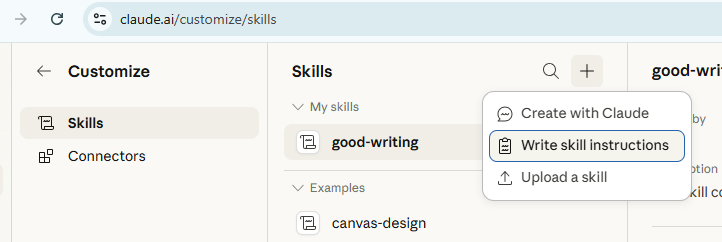
• Within the app, navigate to Customize > Skills and Create new skills
• Select add a new skill and Write skill instructions
• Copy and paste the copy from this file into the skill, making note of the name and description boxes. Feel free to tinker.
• Save your changes.
Note: The instructions in the linked file are Claude’s work, not mine. They came out of months of conversation, where Claude would analyze my style notes, and the file evolved from there. They read a little strangely because of that process. If I’d written them from scratch, they’d sound different. But looking at the file you can see what Claude responds to and how it works.
Claude will apply these instructions to every new conversation going forward. Existing conversations won’t pick up the change, so start a fresh chat to test it. If and when Claude struggles to apply the skill, call it out specifically in the prompt, such as, “Revise this for length using the good writing skill.”
The skill specifies constraints in a few categories and the instructions are plain text. As you go, you can also ask Claude to analyze previous conversations for suggested additions to the skill, which Claude will produce and implement within the chat. Each rule operates independently, so removing one doesn’t affect the others.
Claude processes custom instructions at the start of every conversation, before it generates any output. The instructions function as constraints on the model’s default behavior. The model doesn’t always follow every instruction perfectly and the results vary by task. You will still need to edit.
This new report from Anthropic is depressing at best, as it tries to measure which employment sectors carry the most exposure around AI expansion into the economy. In short, the tech is likely to impact two groups the hardest: educated professional women, and young workers for whom the career ladder will never materialize. In a right-side-up world, this would change the political dynamics of any policy response considerably. In this one, I don’t know.
Anthropic’s positioning here is curious, very god tricky. They are claiming the mantle of responsibility and transparency while predicting an inevitable end nobody wants, that they’re also selling as a service.
I still think much of the forecasting is oversold – the tech performs well in optimized environments, and last mile issues are a perennial concern in any engineering venture because the practical world is non-optimal. Time will tell, and there are big incentives in play. But the hunger and animus around the forecast feel bad.
You might call this a taste test: Obsessed with the story about the McDonald’s CEO and how his LinkedIn-style videos selling the McD’s franchise have escaped containment, leading to one of the funnier CEO/product marketing dynamics in recent history. Burger King’s CEO swooped in, holding widely-marketed listening sessions with customers and to demonstrate his love for the Whopper in contrast with the deeply weird McD’s videos. Must read: Internet long-hauler Katie Notopoulos on how direct-to-public marketing works when the public is more familiar with the product than the org’s leaders.
My teenager thinks fast food is cool and subversive (cue the sound of one hundred moms groaning) and she and her friends regularly talk shop. They are Taco Bell fans and think burger stops are kind of gauche. Not gauche: Baja Blast.
Apparently one thing LLMs excel at is deanonymization at scale. The original promise of pseudonymity online was social and normative, over and above any question of technical depth: decent people don’t try to unmask you, because why. What strikes me today is how what used to be unacceptably antisocial behavior online is now both automated and unremarkable.
Over the last couple of weeks, I asked a couple of chatbots what could be known about me from this pseudonymous site, where I am more intentional about what I choose to reveal and conceal. It pulled the obvious but also drew conclusions based on a few geographic points I’d made in context that were both revealing and correct. I also noticed that it only drew from the top two pages of information - anything beyond page two of posts wasn’t part of the compute. Archives are for humans?
People assume that there is some computer magic on the backend where the LLMs connect all your account logins behind the scenes, but no, in fact it does all this through inference, by linking your digital trail, your friends, your breadcrumbs of likes and hearts and follows, and obvs your posts, into a picture of who you are, practically and demographically.
It’s an old idea, and one I’ve been drawing from while I tinker with Claude. The “god trick” is baked right into the AI interface: one input, one output, an authoritative-seeming answer, offered without named perspectives behind it, trained on text produced overwhelmingly by a narrow demographic who has historically had access to both literacy and publishing, by programmers and new media drawing from the same well. Smushed together, it gives the impression that consensus and authority exists where there are many loose ends and competing ideas in play. Sometimes that’s fine.
I’ve begun to recognize how LLMs can work like autocorrect for ideas, drawing from ranked search sources first before fanning out to more obscure sources, trying to determine and assert what’s important to me, a user known by demographics and data. It feels like a big linguistics machine, which is pretty cool in some regards, but also aggressive in others. The math doesn’t always work to connect me to what I want to find because I am situated in my individual context in ways LLMs are not able to understand, with my memory, in my body, with my unique experiences, which shape and translate meaning for me as I interact with the world (and the web).
I’m seeing a lot of disgust for Indiana in related Bears commentary that troubles me, especially the comments about NWI as a place of blight, beyond consideration or repair, obscuring the stakes behind a regional geography of race and class. Meanwhile, I am glad that people from Chicago suburbs have found occasion to think about their neighbors in Hammond and Gary. There is life outside of Schaumburg.
Indiana’s history as a state is thick with race and class problems, perhaps best captured in the old phrase calling it the “middle finger of the South thrust into the North.” That middle finger reaches right up and touches Chicagoland. Indiana’s policy approach to this dynamic is predictably toxic, having cleaved communities like Hammond and Gary from state investments and statehouse power. Indy loves business and it loves a chance to razz Chicago. Guess why.
This is why we train a jaundiced eye on characterizing working class communities like they’re beyond consideration or redemption. The world isn’t a Costco. People live among the brownfields. I spent a lot of time in this area in my twenties – all my friends in The Region were somehow connected to US Steel, even still. Feel however you feel about the Bears deal, but we don’t do Gary slander in this house.
The last time I went truly viral was in April of 2020 in the height of the COVID shutdown. I posted a tweet and walked away from my phone. By the time I checked back, my notifications were out of control.
The next morning, I got a message from an old friend familiar with my handle. “I think I saw your account on Good Morning America?” Hilariously, there I was, and I couldn’t even claim responsibility for the meme.
I’ve spent most of my time on the internet as a pseudonymous account, using my first name only, or using a handful of handles (incl feministe, fauxrealtho, flotisserie, paired with punny names like “Petty White” and “Frieda People,” a convention from the Tumblr years). Even as a visible personality online, I was only known by my first name and URL and/or handle. In recent years I de- and reactivated some of my socials, so some of these breadcrumbs no longer exist, but I’ll do my best.
Pseudonymity allows writers to explore complex ideas in digital spaces while protecting their identity, location, and other identifying factors, while also maintaining a throughline of identity and storytelling.
There are a lot of trade offs in using a pseudonym, especially around how to claim credit for your work. But people use them because they give you the privacy to be honest, real, weird, authentic, and to escape the creep of modern social media presence into high stakes spaces like the workplace. This dynamic was kind of the impetus behind the era of “weird Twitter,” where people using pseudonymous social handles routinely threw out funny, absurdist one-liners to impress their friends and followers, while taking a turn at the social media slot machine. Not every post or joke lands in a way that converts to numbers, but some do, and it’s fun to try.
I’ve written a little previously about how the English program I was a part of used fiber arts to illustrate the fundamentals of technical writing, but one of their other methods of teaching the internet was through board games. Games, like the internet, and much like writing, provide rules and structure for communication and engagement, but everything that happens inside the container of game board and game play is a mystery until it emerges through human interaction. So goes the internet (and to some extent, so goes AI). Games and gaming were used as a method to think through what it means to create rules of play, then let a community rip through the model – and many of the thinking and skills involved around game design apply in social digital spaces, from chat rooms and Teams channels to the open seas of the WWW. The longer you’ve been playing the slot machine, the more you get a feel for the kind of thing that will get seen and read, and who among your readership will take your content to the next level.
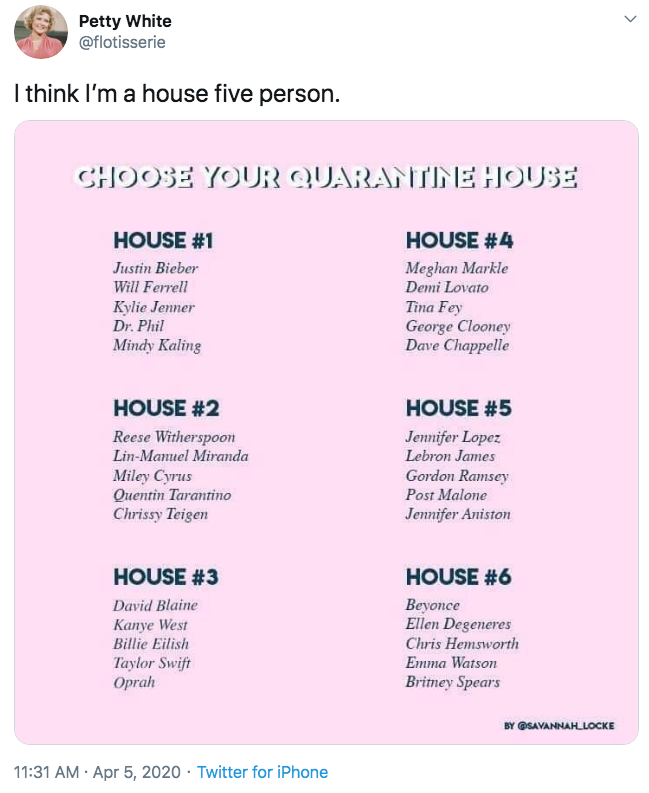
The meme was a list of six hypothetical celebrity households: pick one to quarantine in.
It had been circulating on Facebook, started by a Christian influencer named Savannah Locke. I encountered it deep in a Real Housewives fan group, and felt the pull of a good parlor game. In April 2020, everyone I knew was sitting at home, fretting about the COVID-19 pandemic looming over all of us, so I shared it with minimal ceremony, a couple of buddies with a slightly larger following hit retweet, and within two days the tweet was being cited by The Cut, Time, the Washington Post, ABC News, and others. Know Your Meme documented it for posterity. Several outlets named me as the originator, but trust, I was only trying to delight my friends with low grade Facebook content. I couldn’t find the original meme at the time – Locke appears to have had a name change that scrambled my search. But hey, as these things go, nobody earned a dime or promoted anything weird, so no harm, no foul. Business Insider managed to credit it correctly, so a special kudos to their editor.
The core game mechanism behind the meme is forced choice: constraints generate opinions and opinions generate activity. Each “house” also represents a personality type. House 3 is chaos, House 6 is aspirational, House 5 is the one where someone is definitely cooking and someone is definitely yelling about it. The choices are arbitrary, which invites curiosity about who grouped what and why. In short, this meme offered a light conversation starter at the right time, with low stakes, high personal reveal, and endlessly discussable combinations. It also drew from existing memes and games that are popular online, like “where you sitting” in the proverbial lunch room. This one became news because of the timing and gamability, not because I was particularly clever, but hey.
What does it feel like to go so viral? It’s hilarious, strangely affirming, and also a little crazy-making. It opens the door to a whole lot of wild people and ideas on the internet, not all of them flattering or welcome. Virality is sometimes paired with incredible harassment and requires “more condolences than congratulations.” But as far as this particular experience went – hilarious, whoops, and wow. It just felt like a Lebron James, Post Malone and Jennifer Aniston hang would be a good time.
Haraway (obvs) suggests we stick with the trouble, that sometimes our very presence in the room is what’s required to trouble existing narratives, and that it’s important that share what we learn back to our people at home, whatever that means in our context.
For me: I spend a lot of time at work translating technical ideas and projects in an institutional voice, but on nights and weekends, I’m explaining the ins and outs of the internet to my working class friends and family. Increasingly, I’m asked to explain LLMs and AI and how it relates to their needs around business, the news, entertainment, and as a legal aid.
The “cyborg’s mark” is a metaphor for writing, our duty to translate, and the inevitability of translation through experience. Perhaps staying with the trouble allows us to articulate our experiences in and around the science in ways that both advance our interests and that keep our communities safer. For those of us who straddle multiple worlds, translation is a responsibility.
Widespread AI adoption reopens some basic questions in business: who your audience is, what work can reasonably be automated, what absolutely requires human oversight, and how the service and information environment actually holds together when we shuffle these circumstances around. All this, with many social and environmental risks and a side of existential doom.
I suspect the predictions of economic and social doom are overblown by a lot – in life as in business, generalisms are easy and specifics are hard. Last mile issues remain a reality of nearly any technical or software implementation, and differentiation is in many ways the art of business. There are serious incentives to promising a smooth, profitable near-future, especially around emerging markets, so I feel pretty comfortable forecasting that the era we currently live in is valuation masquerading as value. Instead, I think we should worry more about how the tech changes our relationship to information and to each other.
The dominant conversation is about whether LLMs can write well, but I suspect that’s the wrong frame. Human storytelling will probably always be more interesting than generated storytelling, because humans love quirks and novelty that can’t be produced artificially.
The more consequential change is that AI-generated text doesn’t just sit on the web waiting to be read, and instead feeds back into the system that produced it. It becomes training data, source material, and eventually, architecture. Remember: When an LLM generates text, it’s producing word sequences based on statistical patterns. The output is one plausible version to your prompt, not a definitive one — but it gets indexed, linked, and cited like any other writing. Nothing about its surface tells you it doesn’t carry the same authority.
Researchers call what follows “model collapse,” a feedback loop where models trained on AI-generated content lose touch with the range of human-produced data. The rare and specific details disappear first, then the middle narrows. Eventually what’s left is smooth, confident, increasingly generic text that sounds authoritative whether it’s accurate or not, which becomes the training data for the next round.
I’m thinking about it in terms of the shift from SEO to GEO. SEO preserved a connection between writing and human judgment. Someone wrote content, search engines indexed it, readers got a list of links and decided which to trust by comparing to their own experience and knowledge. This system was gameable through various sleights of hand, but it assumed a reader with agency. The creator’s job was to be easy to find and worth finding. Streaming video complicated this process but still worked with the same basic ideas. Meanwhile, GEO operates on a different premise. The goal isn’t to get found by a person, but to be found by an algorithm assembling a response the user may or may not independently verify.
Consider what happens to the same piece of writing in each system. In the SEO world, your article gets indexed, shows up in search results, someone clicks through, reads it, evaluates whether you or your institution is credible on the topic, maybe skeets it or sends it to a colleague. A human encountered your work, weighed it and decided it was useful, the algo responds and indexes accordingly.
In the old way, the reader moved through the web. AI yanks that experience into a single response from a single interface. We don’t fully understand how AI systems decide what to cite, which makes this power shift feel especially risky. Worse, different people will get different responses from LLMs, even using the same prompts and source materials. We don’t know why.
Fewer entry points to the web means fewer opportunities for diverse or unexpected sources to gain traction, which means the training data gets narrower, which means the outputs get more generic, which means the architecture narrows further, which means fewer perspectives represented in the output. For the reader, it accelerates context collapse in much the same way. Fewer inputs means fewer opportunities to stress test your ideas against new information.
So, what to do?
If generative AI grows as predicted, SEO and GEO will coexist for awhile, and working developers and communicators will need to understand both and how they layer. Strong SEO foundations give you a great head start in AI visibility too, so the fundamentals of good writing and web taxonomy still matter a lot.
But the production of knowledge, the keeping of data, and how it’s all indexed are subjects that are about to become very important, and very political. So I suspect that any fields that touch those topics will also become very important, and very political, very soon.
When I started building websites in the late ’90s, the line between writing and coding didn’t really exist. A person probably learned HTML because she had something to say and needed a place to put it. The internet was free and anonymous and it felt audacious to put your stuff online, like flinging a message in a bottle out to sea. The code was a container for the ideas that rendered them onscreen, and every post and page you published was both a piece of your thinking and a brick in something larger.
People forget that the early web was a writing community. Writers, or bloggers, built their own sites, maintained their own archives, linked to each other deliberately. A blogroll was both a reading list and a show of solidarity, a trackback was a way of saying, “I see you, I’m thinking with you.” The technical architecture - RSS feeds, permalinks, comment threads - existed to organize the writing and the writers’ thoughts, and to push their ideas forward on the open web.
This worked for a time. Communities of writers, most of them without institutional backing or media credentials, built new bodies of knowledge together through interacting as readers and writers, communicating across a foundation of code. The work didn’t stay online. It spilled into conference halls and state houses and newsrooms and policy discussions. As the body of communication built, it created something that accumulated over time. These people influenced mainstream journalism, shaped public conversations, launched careers and movements. In many ways, the national political conditions we face today are a reaction to that movement, and how it allowed regular people to influence the world through the democratization of mass communication.
Midway through the aughts, the brick and mortar publishers and venture capitalists started looking across the landscape, at all the writers creating fantastic content, largely for free, and sucked them into their content and editorial teams. Google Reader lost institutional and financial support as writers moved off the open web and onto publishing platforms, often backed by VC money, that measured the quality of your work by engagement. The addition of algorithmic feeds further broke down this structure – the algorithm doesn’t measure whether your work contributed to shared understanding, but whether it generated a click, a share. The code changed, and the writing changed with it.
The writers changed with it, too. The blogger became the influencer. Bloggers operated in a gift economy of ideas: you wrote to think, to argue, to contribute, and your standing in the wider community came from the quality of your work and contributions over time. Was it a meritocracy? No, but the conditions made it possible for a regular person to talk with experts as peers, which upended traditional power structures around authority and expertise (in both directions, good and bad). Meanwhile, influencers operate in a heavily capitalized attention economy where engagement converts to dollars. The audience is a market to press for money.
The gendered dimension of this shift matters as well. The early blogosphere was full of women writing sharp, rigorous work about politics, culture, parenthood, identity, and technology — work that was explicitly feminist and anti-racist and genuinely moved public conversations. This was the community I helped build (Feministe.us was my project, a community platform of writers and commenters whose coverage and discussion broadly fell under, but was certainly not limited to, the topic of feminism). When the monetized platforms absorbed that energy, the commercial model recast women’s online authority almost entirely in terms of consumer influence. What could we sell? And to whom? The framing around our work went from “this person has important ideas” to “this person can sell things to a niche market.” Meanwhile, men who’d built audiences through tech or political blogging were more likely to be absorbed into mainstream media as columnists and analysts, roles that kept their intellectual authority intact. The influencer label, with all its connotations of superficiality, landed disproportionately on women, and it stuck.
There’s a class piece here, too. The platform model offered something the early blogosphere mostly didn’t — a way to get paid. For women who’d been doing enormous amounts of unpaid intellectual labor building online communities, the question of monetization wasn’t shallow. The implications of information centralization and monetization were as present then as they are now with LLMs and AI. Some people figured out the social platforms and worked their way into viable digital careers. Platforms offered a lot of perks, but all of the perks had a backstop. Corporate interests introduced the problems of advertising, audience and sponsorship, which meant reorienting your individual practice around maximizing your commercial value over and above your intellectual contribution and community management skills. It often meant giving away some or all of your IP rights.
For most people, new system didn’t offer a viable way to get from “respected independent writer” to “respected, protected and compensated writer.” Many of us found ourselves in positions too precarious to take the leap into freelancing and social media, and some, like me, got regular jobs doing regular stuff. Some married money. And in the meantime, some folks figured out how to get into real journalism, which looks much different in 2026.