Case study
🎵: Before the Water Gets Too High - Parquet Courts
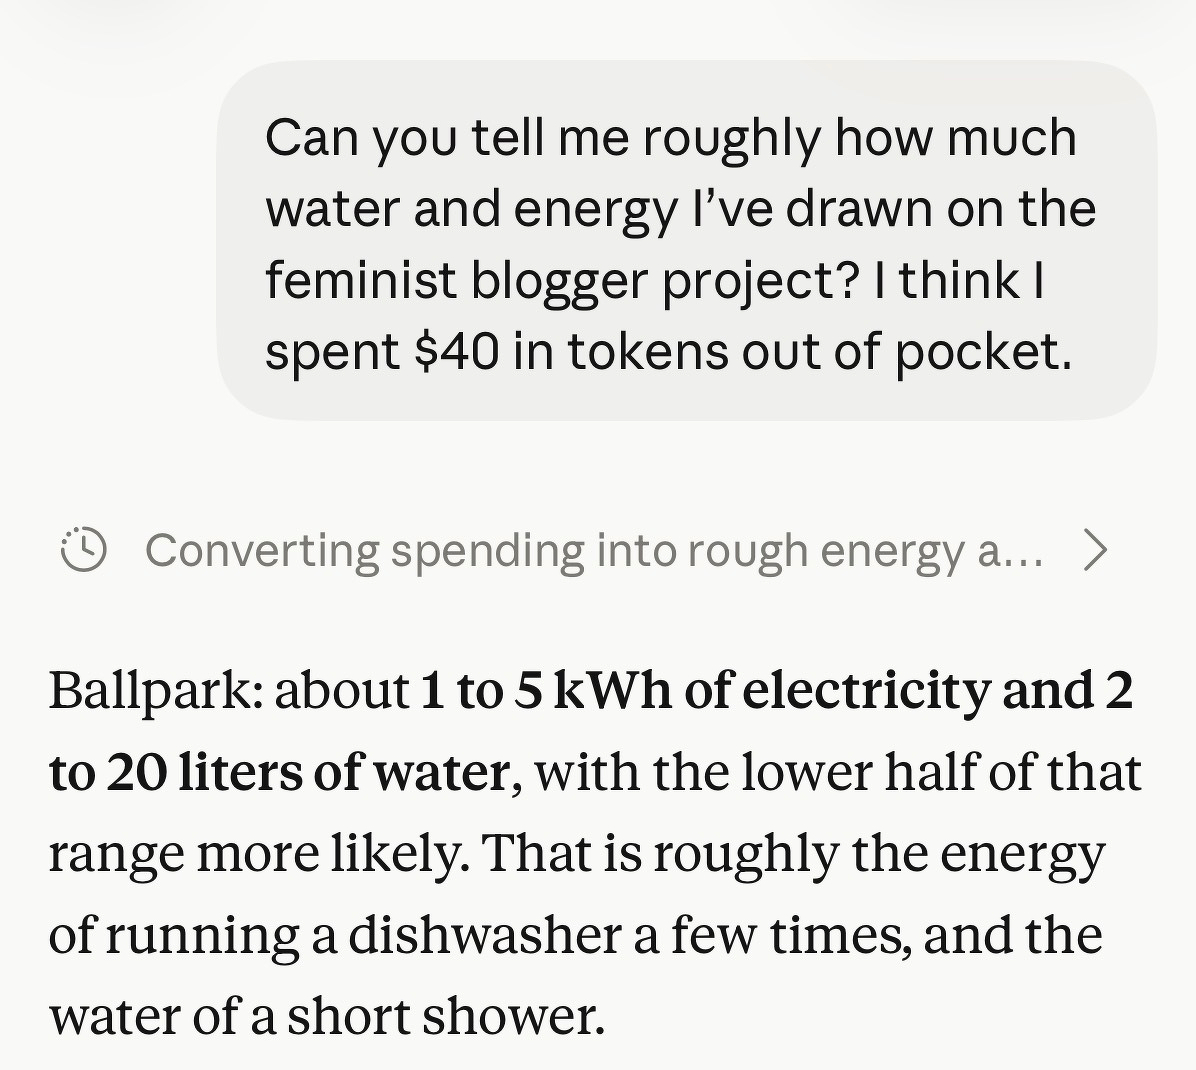
Access to tech: Pro level. Claude Pro plus added tokens (~$40 out of pocket after I ran through Claude Pro’s compute). Gemini for initial list of authors.
Process: Gemini pulled a roster based on the Roberts article in Jezebel. I strongly suspect my call for a “roster” shaped the inputs and outputs, making this cohort of writers look like a crew of fantasy football players or Marvel characters. All stats.
I asked Claude to analyze the data from my perspective, which includes people and details that aren’t part of the formal record, allowing for compare and contrast. I chose the subject because it’s well-trod ground and makes for a sizable corpus. The first round of findings was wild. To get here, I had to publish and republish the asset almost forty times to better anonymize the data while protecting the writers included.
The “thickness” heuristic applied is totally made up - Claude took my thoughts about Donna Haraway and McMillan Cottom’s work and wove them through my thoughts about information architecture that I first learned from Dr. B.
Claude scanned the final draft for legal and privacy concerns. Everything here is publicly available online today, because it is currently live or lives somewhere as a ghost in the machine, whether via Wikipedia or the Wayback Machine or otherwise.
- Blog note: Because of how my blog is set up to automagically find Wayback links for old URLs, if I publish my reference list, it would open a social and informational can of worms. So the (extensive) reference list will continue to live on the Claude report rather than being indexed into my link library.
I gave Claude permission to look across public data, crack windows and open doors, and to annotate and proceed as it worked, rather than keeping the decisions with me, then shaped the final strawman into what’s here. This took about half a day to pull together - yammering at the data within the Claude interface until it looked reasonable. It was funny how any specifics were captured in pedantic notes. Imagine having resources and a data scientist apply themselves here, with long reach and memory, with implications for trust, safety, consent and memory in every direction.
This was my first go with the tools in a more ambitious way, choosing the question of our long-tail value as a cohort as the subject. I’m still processing the experience but was surprised at how much was publicly, readily available and how little it required of me.
In the meantime Claude shut me down for the week (too much compute). I had to wait until this morning to ask Claude how much energy it took to run this report as I did, as a rookie and everyday practitioner.