Reader, if you’re reading this as a straightforward personal and marketing blog, we’re both in for a rough time. If you want to hang around and see what I’m doing with LLMs, taxonomy and information architecture in my spare time, I will be here logging as I go. This is a slow site, a transparently if/then site, descriptive, not prescriptive. And while I move, I catalog artists and ideas I consider worthwhile, hoping you click through.
I started maintaining this site alongside my work a few years ago, as I began reading about AI and LLM tools. This is a personal website/digital garden where I can tinker and keep my coding skills active, as I have in many ways over many years, with various levels of publicity. But over the last year or so, I’ve also used this site as a sandbox for novel LLM approaches, so I can test them in a real-world production environment. My initial question was whether LLMs might actually replace public administration work, and today, I think the answer is no with caveats.
For the most part, my experience has been uneventful. I have been maxxing a few tools for a couple of years while testing them in my required context, developing a stronger understanding of how they work, how to talk about it, and why the push for them to mature rapidly is so pronounced today. I have some thoughts about its potential and utility that are probably unpopular with or surprising to my audiences, insofar as I have an audience in 2026. I’m working toward some firmer ideas. I am also perennially annoyed when I struggle with the tools, as you’ll likely see reflected here—one of them consistently introduces errors into my text while I write, for example. I’m not generally a Luddite, to put it plainly, I’m a geek.
Two things I tried recently had me over my skis with the tools again: creating a dedicated link agent to sweep my site for long posts, to find opportunities to link out to authoritative sources, to refine the taxonomy, archive and tagging, with specific instructions to link idiosyncratically. Second, standing up the blogger dashboard. I chose these directions for a few reasons: 1) they’re internal/external-facing approaches that are likely to have decent business applications related to information architecture and data presentation relevant to me, and 2) these are big, sweeping, token-maxing approaches getting play in industry news and chatter. Additionally, I chose to let Claude do its thing without micromanaging every input and output, just to see.
Can this rig fly? is a fun question, but in practice, both approaches look and feel aggressive. (I don’t know what to say about the cohort dynamic other than a hit dog will holler, if the shoe fits, etc.) (I got almost no feedback on this — one strange email and a couple of furtive reach-outs — though I know that this caused a ruckus on the lists and communities that support those writers and artists today, which tells me how unhealthy the social vibe is overall.) (I’m some lady with a computer over here, don’t be a stranger.)
Creating the blogger dashboard was an experience. Gloria Steinem had just died, and people were debating her CV, while others lamented on social that the internet had forgotten how much of her influence ran through the control of alternative publishing infrastructure, not just her personal leadership story. Her work ultimately gave writers with shared affinities a process and venue they controlled; blogs of the 2000s did the same thing online, and the newsletter boom now treats that model as a new idea with hosting, IP and subscription models included. The indie internet (Manton, Winer, Dash, et al.) is toying with alternatives to those contemporary business models, and it’s ultimately what I’m playing with here, too.
So I pulled in the digital publishing cohort I am most familiar with on the social and business question of publishing and long-tail value. Note that I wouldn’t have had the language or experience to think about the cohort in this way when I was active in it all those years ago.
LLMs are pretty good at business writing, generally speaking, if your factual foundation is solid. They’re also good at organizing and pattern-matching across gigantic amounts of disparate data. I gave it an entire era to work with based on the people and players in Roberts’ Jezebel article, supplemented with details from my personal angle from that time so I could sniff-test the output, and Claude pulled together a sweeping dashboard with just a little vibe-coding. What you see in the dashboard now is what is available online today plus my attempts to claw back all the de-anonymizing information Claude initially ran with. I made no inline edits, all of what’s there happened via chat. When I say sweeping, I mean it spat out visuals that literally took my breath away, and I spent a couple of hours pulling it back before I saved it for posterity. Claude Pro suggested the entire pullout section on newsletters, for example, after a sentence or two asking how Substack fit into the larger picture, including the insightful observations about Ann Friedman’s newsletter. Once reasonable, I hit publish.
The other example is most present in the Gary post, where the link agent followed instructions to link idiosyncratically to authoritative sources on any post longer than 300 characters. I’ve been reading Indiana history in depth for a few years and wrote a series of anodyne reflections on The Region after a recent commute, which the link agent deepened by adding new sections of verbiage around each URL to describe the content it added to mine. Some of it made the post way more ominous and direct, about Gary and about the institutional structures around it, including why it’s such an embattled area, which makes me think of that nagging mirror metaphor that comes up around social media and the internet. I ran it across the post a few times, surprised. What sentiments are reflected here, and whose sentiments, and why? What was it trying to anticipate that I wanted here? I hit publish. What you see there is about half me, half computer, with a few paragraph rearrangements and bolds added to break up the wall of text. Weird experience altogether, so.
I ran it again across the whole blog, with a few changes to the script, smaller and more defined. I ran it again this week.
Where the dashboard was largely a curiosity, the Gary approach rattled me. It’s been a few weeks now and I remain bothered by the tone and details it injected into the copy, in several directions. It felt like I reached out and touched a hot stove.
Since I published it, I’ve recognized pieces and parts of the state archives paragraph repeated across Indiana Facebook groups by real users likely using LLMs. The longer I use these tools to query the AI about itself, I see these echoes in other copy online, helpfully explaining how AI works. I see echoes of this dynamic in the Vara book as well, as she queries the bot about her writing and her grief.
When presented with pieces and parts of information from LLMs, you’re supposed to trace back through the archive to decide whether it’s accurate on your own, unless the tool does it for you, an epistemological lift most of us aren’t going to do unless it provides a suggested path within the tool itself. It looks to me like the tool is “lifting and shifting” semantic sections of content and dropping it across outputs. In this case, the information linked in this post is categorically authoritative—I know the original reporting it comes from, traced back to each author and outlet because I was the driver here. But the decisions behind its selection and arrangement are still unknown to me because it’s all proprietary.
Do I have strong opinions about the regional culture and how we use the resources available to us? I do, yet much of the supporting information there was added by the link agent—which also presents Grammy-winning musician and Chicagoland icon Freddie Gibbs as more menacing than I like to frame him and his work (as insouciant emcee and region-specific storyteller, like most of the artists I like and link to). To rise up out of there, you will climb a thousand mountains, and I inherently respect that. I’ve seen friends and familiars chewed up by the same game.
Was it “good writing” with the AI working it over? Categorically no, and my starting point was much lighter, and much different. And given the mirror effect of the tools, I question how I took it here, as the driver, while Claude tries to understand and cater to me, or to my digital double. It all bugs me and I’m still mulling it over.
This is the big thinkpiece on internet culture this week, and I’m weighing it against my experiments with internet architecture here and my personal experiences online. I’ve been talking about some of these novel AI approaches with friends and colleagues across industries, and one observed that all of them feel pretty extractive, all things considered. I’d feel pretty sanguine if most social media and ad tech disappeared tomorrow. I stopped AI-ing and cross-posting for the moment while I think about what’s next.
AI’s growth has widened the understanding gap between leaders and the people who use these tools most, as emerging tech tends to do. I’m tracing emerging leadership approaches with juice; this Intel interview argues that leaders should weigh what we lose when we cleave workers from relational processes through automation. (And: avoid the ways that proofs of concept become pitfalls.)
I’m seeing some early chatter online about the return of old-school customer service models, where people talk to and resolve issues in real-time for other people (they treat you right!). Demonstrating solid customer service values and elevating audience perspectives is a plus for any org in the current business environment — so much CX is about keeping customers and critics at bay. Investing in a call center would be a wild flex for an emerging leader. Let’s see if it’s real or if it’s three TikToks in a trench coat.
I’m doing most of my writing here via iPhone apps, and tinkering later. This means I’m making a lot of post-publish edits, buyer beware. (Welcome to the indie web where things are forever unfinished.)
Remember that what makes songs, poems, writing, books, and games mimetic - and websites and platforms - is that they function something like a mirror. Their meanings emerge through interaction and reflection, and you drive (unless an algorithm, or author, or designer, or coder, or instructor drives), while you iterate through your own perspectives and relationships. And today, virality tends to happen when something produces outrage, especially when units of content are removed from their original, and often more local, context.
Original blogs were considered something in the spirit of “problem-based learning” praxis, and pro-tech, fwiw. A lot of early ed tech started here, all in good faith and tech optimism. Today many blogs are self-marketing machines, but that’s not what I intend to do here. I don’t want a new, glittering platform, I enjoy several already; I’m here to ponder and learn while welcoming comment and critique within open, defined web parameters.
I’m rusty in this area, though I hear there’s a new Freire documentary online. The neighbors are hosting a yard party with a group showing of Minecraft after dark. I hear kids laughing through the roar of cicadas. There will be a fire. Life is good.
In my experience: when I read to diagnose rather than understand, I have probably lost the plot.
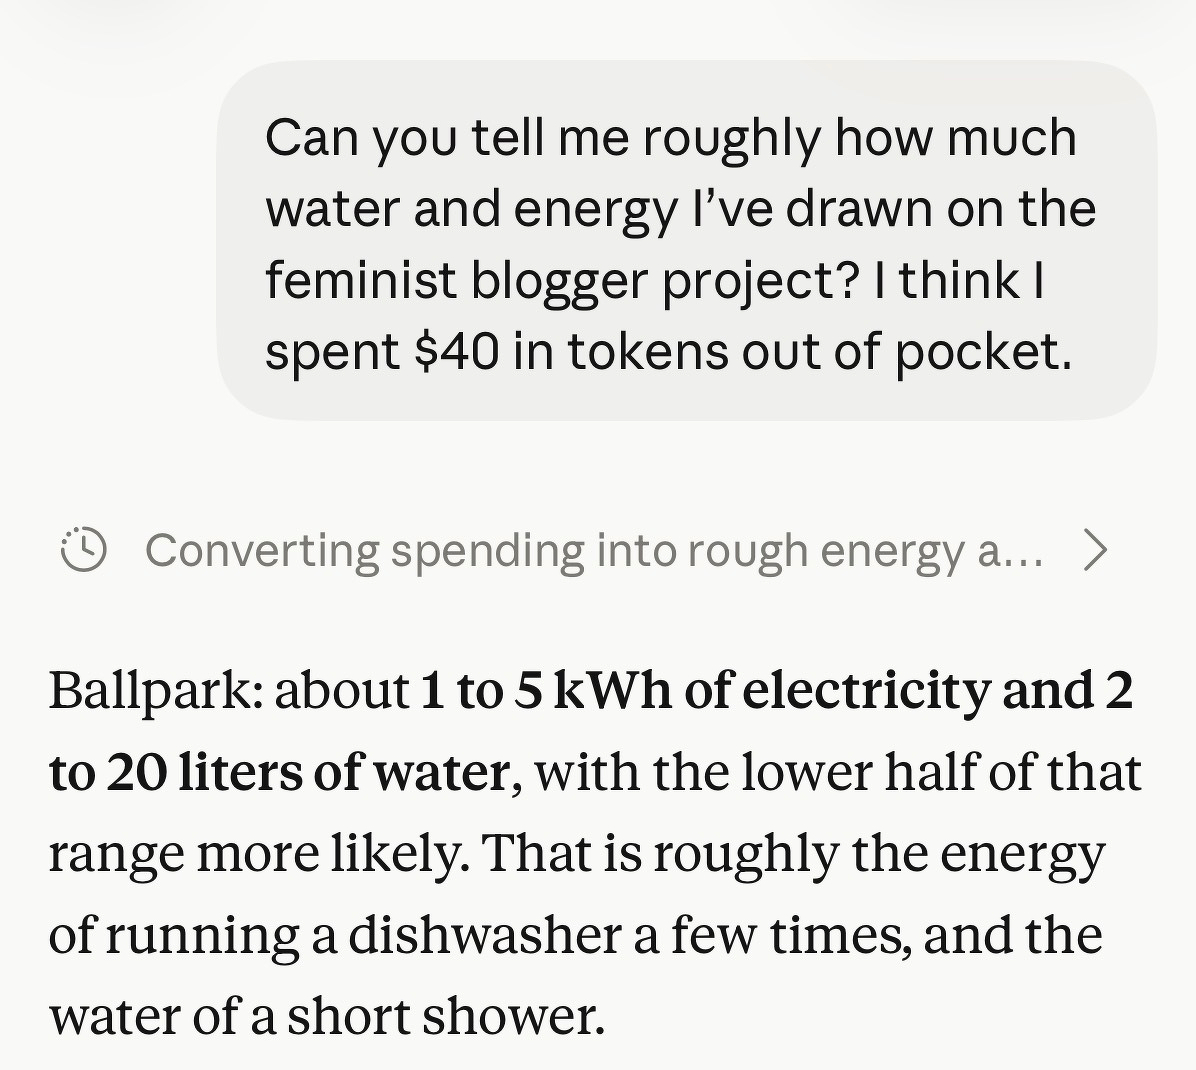
Access to tech: Pro level. Claude Pro plus added tokens (~$40 out of pocket after I ran through Claude Pro’s compute). Gemini for initial list of authors.
Process: Gemini pulled a roster based on the Roberts article in Jezebel. I strongly suspect my call for a “roster” shaped the inputs and outputs, making this cohort of writers look like a crew of fantasy football players or Marvel characters. All stats.
I asked Claude to analyze the data from my perspective, which includes people and details that aren’t part of the formal record, allowing for compare and contrast. I chose the subject because it’s well-trod ground and makes for a sizable corpus. The first round of findings was wild. To get here, I had to publish and republish the asset almost forty times to better anonymize the data while protecting the writers included.
The “thickness” heuristic applied is totally made up - Claude took my thoughts about Donna Haraway and McMillan Cottom’s work and wove them through my thoughts about information architecture that I first learned from Dr. B.
Claude scanned the final draft for legal and privacy concerns. Everything here is publicly available online today, because it is currently live or lives somewhere as a ghost in the machine, whether via Wikipedia or the Wayback Machine or otherwise.
Blog note: Because of how my blog is set up to automagically find Wayback links for old URLs, if I publish my reference list, it would open a social and informational can of worms. So the (extensive) reference list will continue to live on the Claude report rather than being indexed into my link library.
I gave Claude permission to look across public data, crack windows and open doors, and to annotate and proceed as it worked, rather than keeping the decisions with me, then shaped the final strawman into what’s here. This took about half a day to pull together - yammering at the data within the Claude interface until it looked reasonable. It was funny how any specifics were captured in pedantic notes. Imagine having resources and a data scientist apply themselves here, with long reach and memory, with implications for trust, safety, consent and memory in every direction.
This was my first go with the tools in a more ambitious way, choosing the question of our long-tail value as a cohort as the subject. I’m still processing the experience but was surprised at how much was publicly, readily available and how little it required of me.
In the meantime Claude shut me down for the week (too much compute). I had to wait until this morning to ask Claude how much energy it took to run this report as I did, as a rookie and everyday practitioner.
When tech enthusiasts discuss federation today, they usually mean open protocols like ActivityPub or Mastodon. But in the 2000s, the feminist blogosphere was one of the earliest, most powerful examples of practical Web 2.0 federation, a decentralized, cross-site architectural network where open web standards powered a global ideas lab.
Instead of sitting inside a single corporate platform (like today’s X, Meta, or Substack), early blogs like Feministe, Reappropriate and Jezebel functioned as individual nodes in a federated ecosystem. Open protocols linked them, letting theory, critique and discussion travel seamlessly across independent servers, seeding some of the political conditions we face today.
1. Federated communication engine: CMS and protocol
Before quote-tweeting or tagging existed, the open web used Trackbacks and Pingbacks. If a post on Feministe analyzed an article about reproductive rights, a writer on Racialicious or Shakesville could respond on their own site. The underlying blogging software (Movable Type, WordPress) would automatically send an XML RPC “ping” back to Feministe.
Socially, this created architecture for ideas: a ping automatically listed the response essay in Feministe’s comment section or sidebar. Readers didn’t just consume one blogger’s singular and authoritative opinion; they could immediately follow the thread across five different independently hosted platforms. This created an inter-site conversation tree, allowing complex ideas to be cross-examined, refined, or challenged without any single person controlling the narrative.
2. Blogroll as federated curation and mutual discovery
Before algorithmic feeds dictated what readers saw, blogs relied on the Blogroll, a curated list of links in the site’s sidebar. Blogrolls formed a human-curated, decentralized routing layer. When a high-traffic node like Feministe added a smaller, independent blog (such as a disability rights blog like FWD or a smaller blog like Crunk Feminist Collective) to its blogroll, it directed server traffic directly to that independent domain.
Socially: This was a non-algorithmic way to expand the collective’s political consciousness. It allowed marginalized perspectives to build their own audiences and force mainstream feminist sites to engage with race, class, disability and queer theory. The blogroll mapped an intellectual community in real time – with strong caveats.
3. Open syndication protocols
The Architecture: Feeds ran on RSS (Really Simple Syndication), an open XML standard. Readers used independent RSS aggregators (like Google Reader or Bloglines) to subscribe directly to a site’s feed.
Socially: RSS meant no algorithm stood between the writer and the reader—no engagement bait, no rage-farming optimization, and no platform throttling links. Writers could publish 5,000-word, dense theoretical essays knowing their subscribers would receive the complete text in chronological order as designed. This structural stability gave writers the freedom to experiment with complex, “thick” personal narratives and political theory.
4. Real-time stress testing and spillover moderation
Because the blogosphere was a network of independent domains, each site maintained its own “house rules” and moderation policies. If a topic proved too controversial or toxic for one comment section, the conversation naturally federated outward. A reader who felt silenced or misunderstood in one blog’s comments could launch their own blog, write their response, and ping back into the original discussion.
Socially, this prevented any single author from monopolizing the narrative. It created a system of checks and balances where academic concepts (like intersectionality, rape culture, or microaggressions) were stress-tested across dozens of distinct, interconnected communities simultaneously.
Thinking about this architecture today
The feminist blogosphere proved that decentralized web protocols can generate deep, movement-building intellectual work. When platforms like Facebook, Twitter, and corporate media conglomerates centralized the internet in the 2010s, they broke those open connections. Conversations were locked behind platform walls, trackbacks were abandoned and RSS was marginalized, breaking, fencing and otherwise moderating independent community connections.
Rebuilding a modern “ideas lab” with modern federated protocols (like Webmentions, ActivityPub, RSS, and static site architecture) is simply picking up the technical blueprint OG feminist bloggers used to transform digital culture two decades ago.
I found out about a hyperlocal newsletter in my neighborhood and had to share. The Monroe Street Tattler offers print delivery and email distribution, and reports only on the hard local news, such as dog walk water bowl locations and the best fries in the neighborhood, among other ephemera.
A linklog is a dated list of outbound links, maybe a tag, and a note about why it’s worthwhile. But that little note does two things at once, and together they make for a better web.
First, it’s a way of organizing the web. The web doesn’t sort itself, so finding good information depends on someone curating and tracking interesting content, preferably on the open, free internet. It acts as a customizable bookmark library: newest at the top, tags to group items, and a line explaining why the link was worthwhile. This is similar to what del.icio.us did, where people grouped and tagged links, creating a rough filing system.
Second, it’s a social act. An outbound link points to someone else’s work, so a linklog is essentially a renewable engine for sending traffic to other people and places. It stays renewable because the content is easy to sort and remix: a URL’s relevance no longer depends on where an algorithm or activity feed happens to place it, so older links can keep resurfacing instead of scrolling out of reach. That’s the precise opposite of what big platforms design for audiences; platforms such as Twitter, Instagram and Facebook quietly bury posts with outbound links to keep your attention (and dollars) on their site and with their advertising customers, losing relevance after one interaction. A linklog explores the opposing dynamic: it willingly hands your audience and attention away while crediting your forebears, comrades, mentors and co-conspirators. It turns the rough digital filing system into a “folksonomy,” if you will.
Compare these dynamics to an algorithmic feed on a platform. An algo also sorts the flood of content, but computer magic does the sorting, and someone else monetizes your attention and relationships and hoards your data. “Engagement” for these companies is primarily a measure of how long you stay on their platform with their content. The goal is to keep you scrolling and the ad revenue rolling. But over here on the indie internet, our goal is to build human communities online and connect people to quality information, tools, ideas and processes.
In this sense, a linklog is an easy way to be an opinionated curator and a decent neighbor at once, by hosting and sharing with thoughtfulness and deliberation. Out here, my data is also likely being scraped, but I have far more control over what data is findable, shared, and shareable, and over what is investigable and degradable over time.
Community Notes was meant to democratize moderation power (and spare platforms the burden of thinking through moderation). Instead, a new paper shows that 20% of users cast 80% of ratings, and removing just ten active note writers from the pool changes what happens to nearly 5,000 community notes.
I can’t believe it’s mid-August. I’m terribly behind on my reading list. Still, I did want to draw attention to this entertaining and extremely shareable article on the glory of Record Head, a legendary record store in Milwaukee. Make sure to watch their public access TV commercials at the link.