Reader, if you’re reading this as a straightforward personal and marketing blog, we’re both in for a rough time. If you want to hang around and see what I’m doing with LLMs, taxonomy and information architecture in my spare time, I will be here logging as I go. This is a slow site, a transparently if/then site, descriptive, not prescriptive. And while I move, I catalog artists and ideas I consider worthwhile, hoping you click through.
I started maintaining this site alongside my work a few years ago, as I began reading about AI and LLM tools. This is a personal website/digital garden where I can tinker and keep my coding skills active, as I have in many ways over many years, with various levels of publicity. But over the last year or so, I’ve also used this site as a sandbox for novel LLM approaches, so I can test them in a real-world production environment. My initial question was whether LLMs might actually replace public administration work, and today, I think the answer is no with caveats.
For the most part, my experience has been uneventful. I have been maxxing a few tools for a couple of years while testing them in my required context, developing a stronger understanding of how they work, how to talk about it, and why the push for them to mature rapidly is so pronounced today. I have some thoughts about its potential and utility that are probably unpopular with or surprising to my audiences, insofar as I have an audience in 2026. I’m working toward some firmer ideas. I am also perennially annoyed when I struggle with the tools, as you’ll likely see reflected here—one of them consistently introduces errors into my text while I write, for example. I’m not generally a Luddite, to put it plainly, I’m a geek.
Two things I tried recently had me over my skis with the tools again: creating a dedicated link agent to sweep my site for long posts, to find opportunities to link out to authoritative sources, to refine the taxonomy, archive and tagging, with specific instructions to link idiosyncratically. Second, standing up the blogger dashboard. I chose these directions for a few reasons: 1) they’re internal/external-facing approaches that are likely to have decent business applications related to information architecture and data presentation relevant to me, and 2) these are big, sweeping, token-maxing approaches getting play in industry news and chatter. Additionally, I chose to let Claude do its thing without micromanaging every input and output, just to see.
Can this rig fly? is a fun question, but in practice, both approaches look and feel aggressive. (I don’t know what to say about the cohort dynamic other than a hit dog will holler, if the shoe fits, etc.) (I got almost no feedback on this — one strange email and a couple of furtive reach-outs — though I know that this caused a ruckus on the lists and communities that support those writers and artists today, which tells me how unhealthy the social vibe is overall.) (I’m some lady with a computer over here, don’t be a stranger.)
Creating the blogger dashboard was an experience. Gloria Steinem had just died, and people were debating her CV, while others lamented on social that the internet had forgotten how much of her influence ran through the control of alternative publishing infrastructure, not just her personal leadership story. Her work ultimately gave writers with shared affinities a process and venue they controlled; blogs of the 2000s did the same thing online, and the newsletter boom now treats that model as a new idea with hosting, IP and subscription models included. The indie internet (Manton, Winer, Dash, et al.) is toying with alternatives to those contemporary business models, and it’s ultimately what I’m playing with here, too.
So I pulled in the digital publishing cohort I am most familiar with on the social and business question of publishing and long-tail value. Note that I wouldn’t have had the language or experience to think about the cohort in this way when I was active in it all those years ago.
LLMs are pretty good at business writing, generally speaking, if your factual foundation is solid. They’re also good at organizing and pattern-matching across gigantic amounts of disparate data. I gave it an entire era to work with based on the people and players in Roberts’ Jezebel article, supplemented with details from my personal angle from that time so I could sniff-test the output, and Claude pulled together a sweeping dashboard with just a little vibe-coding. What you see in the dashboard now is what is available online today plus my attempts to claw back all the de-anonymizing information Claude initially ran with. I made no inline edits, all of what’s there happened via chat. When I say sweeping, I mean it spat out visuals that literally took my breath away, and I spent a couple of hours pulling it back before I saved it for posterity. Claude Pro suggested the entire pullout section on newsletters, for example, after a sentence or two asking how Substack fit into the larger picture, including the insightful observations about Ann Friedman’s newsletter. Once reasonable, I hit publish.
The other example is most present in the Gary post, where the link agent followed instructions to link idiosyncratically to authoritative sources on any post longer than 300 characters. I’ve been reading Indiana history in depth for a few years and wrote a series of anodyne reflections on The Region after a recent commute, which the link agent deepened by adding new sections of verbiage around each URL to describe the content it added to mine. Some of it made the post way more ominous and direct, about Gary and about the institutional structures around it, including why it’s such an embattled area, which makes me think of that nagging mirror metaphor that comes up around social media and the internet. I ran it across the post a few times, surprised. What sentiments are reflected here, and whose sentiments, and why? What was it trying to anticipate that I wanted here? I hit publish. What you see there is about half me, half computer, with a few paragraph rearrangements and bolds added to break up the wall of text. Weird experience altogether, so.
I ran it again across the whole blog, with a few changes to the script, smaller and more defined. I ran it again this week.
Where the dashboard was largely a curiosity, the Gary approach rattled me. It’s been a few weeks now and I remain bothered by the tone and details it injected into the copy, in several directions. It felt like I reached out and touched a hot stove.
Since I published it, I’ve recognized pieces and parts of the state archives paragraph repeated across Indiana Facebook groups by real users likely using LLMs. The longer I use these tools to query the AI about itself, I see these echoes in other copy online, helpfully explaining how AI works. I see echoes of this dynamic in the Vara book as well, as she queries the bot about her writing and her grief.
When presented with pieces and parts of information from LLMs, you’re supposed to trace back through the archive to decide whether it’s accurate on your own, unless the tool does it for you, an epistemological lift most of us aren’t going to do unless it provides a suggested path within the tool itself. It looks to me like the tool is “lifting and shifting” semantic sections of content and dropping it across outputs. In this case, the information linked in this post is categorically authoritative—I know the original reporting it comes from, traced back to each author and outlet because I was the driver here. But the decisions behind its selection and arrangement are still unknown to me because it’s all proprietary.
Do I have strong opinions about the regional culture and how we use the resources available to us? I do, yet much of the supporting information there was added by the link agent—which also presents Grammy-winning musician and Chicagoland icon Freddie Gibbs as more menacing than I like to frame him and his work (as insouciant emcee and region-specific storyteller, like most of the artists I like and link to). To rise up out of there, you will climb a thousand mountains, and I inherently respect that. I’ve seen friends and familiars chewed up by the same game.
Was it “good writing” with the AI working it over? Categorically no, and my starting point was much lighter, and much different. And given the mirror effect of the tools, I question how I took it here, as the driver, while Claude tries to understand and cater to me, or to my digital double. It all bugs me and I’m still mulling it over.
This is the big thinkpiece on internet culture this week, and I’m weighing it against my experiments with internet architecture here and my personal experiences online. I’ve been talking about some of these novel AI approaches with friends and colleagues across industries, and one observed that all of them feel pretty extractive, all things considered. I’d feel pretty sanguine if most social media and ad tech disappeared tomorrow. I stopped AI-ing and cross-posting for the moment while I think about what’s next.
I book-maxxed in 2026 thanks to finally caving and buying an eReader. No, I don’t want to talk about it, and yes, it turns out I like to read a lot more these days when it’s on a screen.
My energy for books is flagging after a speed run, though I expect to finish another 2-3 before the end of the year. I am enjoying Searches: selfhood in the digital age by Vauhini Vara — she is doing something similar to what I’m noodling with here, arranging a vignette of personal reflections with common-place book-keeping. It also reminds me a little of Ullman, in that she captures the texture of a tech era through first-person writing (interspersed with some revealing chatter using ChatGPT). Related: getting cozy with Ethan Mollick.
I am also 100% committed to finishing the Edmund Fitzgerald book in November, as assigned by Beloved Book Club. There will be jokes.
Music note: I was given two music assignments in recent weeks: my team directed me to listen to the latest Taylor Swift album, and my kiddo curated a playlist of Lucki songs with specific instructions to listen to him using headphones. I liked pieces and parts of both artists quite a lot, playlists updated accordingly.
AI’s growth has widened the understanding gap between leaders and the people who use these tools most, as emerging tech tends to do. I’m tracing emerging leadership approaches with juice; this Intel interview argues that leaders should weigh what we lose when we cleave workers from relational processes through automation. (And: avoid the ways that proofs of concept become pitfalls.)
I’m seeing some early chatter online about the return of old-school customer service models, where people talk to and resolve issues in real-time for other people (they treat you right!). Demonstrating solid customer service values and elevating audience perspectives is a plus for any org in the current business environment — so much CX is about keeping customers and critics at bay. Investing in a call center would be a wild flex for an emerging leader. Let’s see if it’s real or if it’s three TikToks in a trench coat.
Knowing what we know about LLMs and how they work today on the mostly-centralized web, I think the next few years are going to be an interesting time to be a writer with an independent website.
Within this report, the LLM reflected my concern about my old blog appearing to be the center of these old networks. In fact, this is an effect of me pouring into the model.
It says:
The compiler appears on this page more often than her place in the blogosphere warrants. That emphasis is an effect of how large language models work: the models that compiled the page (Gemini and Claude) build their output from the material in front of them, and the compiler’s recollections were the fullest source they had, so her name attached to claims as their source and her own path filled more of the page than the record supports. This version names her less and marks firsthand claims as “firsthand.”
I asked Claude why LLMs work this way:
Context outweighs training data. A model has two sources: what it absorbed in training and what sits in the prompt. For feminist blogs of the 2000s, the training data is thin and scattered. Many of those blogs are dead links, partial Wayback captures, or sites that only show up as names in other people’s blogrolls. Your recollections, by contrast, were dense, specific, and right there in the context window. Generation is conditioned on that context, so the model draws the words, names, and connections it gives the highest probability from the prompt far more than from faint training memories. The fullest source sets the terms for everything else.
Source and subject merge. When you write “I remember that X linked to Y,” the text contains two facts: something happened between X and Y, and you are the one reporting it. [LLMs are semantically responsive to triangulation of meaning ~LB] Models don’t track provenance well, so the narrator’s name tends to drift into the content. “Compiler recalled” turns into “Compiler was part of,” and the person reporting a network becomes a node in that network. Your note’s phrase “her name attached to claims as their source” describes this accurately. It is a familiar failure in summarization, and it gets worse as the documents get longer.
Detail density reads as importance. Where the record is thin, the model fills gaps by extending whichever thread has the most material, and that thread was your path. A blog you described in four sentences gets more space, more connections, and more apparent centrality than one you mentioned in passing. The page ends up showing how much the compiler knew about each blog. That is a different quantity from each blog’s place in the network, and nothing in the process separates the two.
Training data favors the same names. Feministe is one of the better-documented blogs from that period. It was archived, cited in academic work, and linked from other surviving blogs. So the model’s background knowledge already over-represents the blogs that left records, and your recollections reinforced that bias instead of offsetting it.
Tuning rewards engagement with user material. Preference training rewards responses that use what the user supplied. A model that set aside half your recollections as over-represented would probably have been rated lower during training, so it leans toward incorporating whatever it was given.
Two models compound the effect. Gemini’s output became Claude’s input. The second model received a document that was already weighted toward you and treated that weighting as part of the record. Each pass inherits the previous pass’s emphasis and adds no correction, because neither model has an outside reference point.
The compiled page presented one person’s situated knowledge as a neutral overview, which is close to Haraway’s “god trick.” Labeling claims “firsthand” puts the situation back on the page. For the notes you plan to write, a useful test is whether that label changes how the model weights claims when it compiles the next version, or only how readers weight them. I expect it changes only readers’ weighting unless the prompt also tells the model to give unsourced firsthand claims less space than claims with external citations.
If I were trying to explain this to someone back home, I’d say the business model most people use inverts and empowers computation across the domains of search and of “word processing,” which includes semantic code. And because of the dynamics around the single-user interface, it lends more data authority to those outputs than is perhaps warranted. The vision is that the machine does the writing and the author steers, not unlike driving a car or using a hammer.
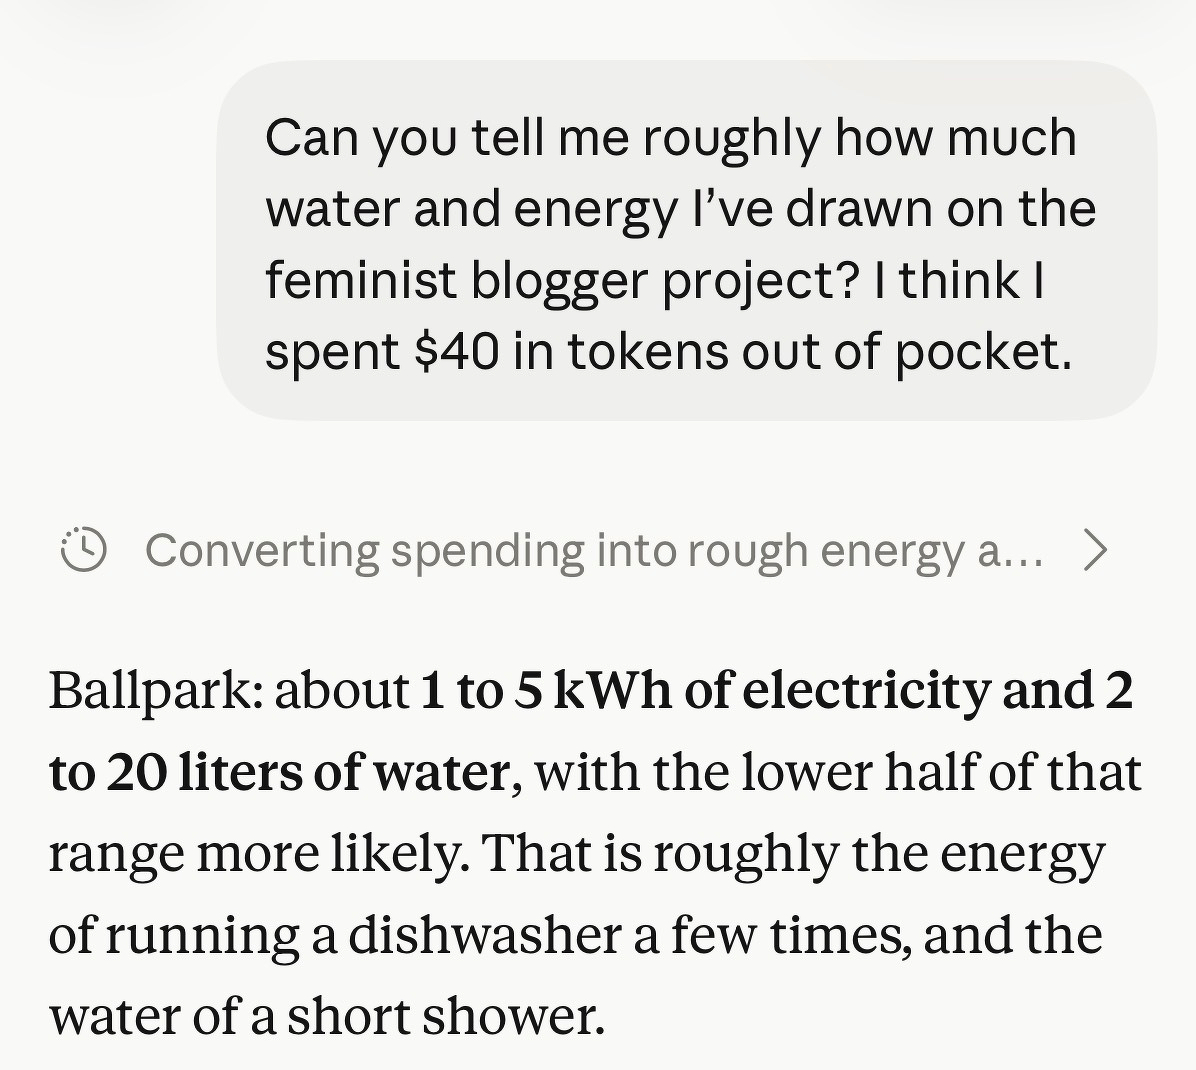
Access to tech: Pro level. Claude Pro plus added tokens (~$40 out of pocket after I ran through Claude Pro’s compute). Gemini for initial list of authors.
Process: Gemini pulled a roster based on the Roberts article in Jezebel. I strongly suspect my call for a “roster” shaped the inputs and outputs, making this cohort of writers look like a crew of fantasy football players or Marvel characters. All stats.
I asked Claude to analyze the data from my perspective, which includes people and details that aren’t part of the formal record, allowing for compare and contrast. I chose the subject because it’s well-trod ground and makes for a sizable corpus. The first round of findings was wild. To get here, I had to publish and republish the asset almost forty times to better anonymize the data while protecting the writers included.
The “thickness” heuristic applied is totally made up - Claude took my thoughts about Donna Haraway and McMillan Cottom’s work and wove them through my thoughts about information architecture that I first learned from Dr. B.
Claude scanned the final draft for legal and privacy concerns. Everything here is publicly available online today, because it is currently live or lives somewhere as a ghost in the machine, whether via Wikipedia or the Wayback Machine or otherwise.
Blog note: Because of how my blog is set up to automagically find Wayback links for old URLs, if I publish my reference list, it would open a social and informational can of worms. So the (extensive) reference list will continue to live on the Claude report rather than being indexed into my link library.
I gave Claude permission to look across public data, crack windows and open doors, and to annotate and proceed as it worked, rather than keeping the decisions with me, then shaped the final strawman into what’s here. This took about half a day to pull together - yammering at the data within the Claude interface until it looked reasonable. It was funny how any specifics were captured in pedantic notes. Imagine having resources and a data scientist apply themselves here, with long reach and memory, with implications for trust, safety, consent and memory in every direction.
This was my first go with the tools in a more ambitious way, choosing the question of our long-tail value as a cohort as the subject. I’m still processing the experience but was surprised at how much was publicly, readily available and how little it required of me.
In the meantime Claude shut me down for the week (too much compute). I had to wait until this morning to ask Claude how much energy it took to run this report as I did, as a rookie and everyday practitioner.
Does this feel slimy? I concede it may. But it demonstrates the value of personal writing and thoughtful design in digital spaces despite its many gaps and flaws.
Enjoy and tinker. Feedback is welcome. I’ll have some notes on my approach and why many of these findings remain heavily qualified in the coming weeks.
Konstantinos Komaitis has started a ten-part series at Techdirt called The Metric Is Not the Mission. It traces how Big Tech went from building the open internet to reshaping it around its own metrics and incentives. Part I argues that the recurring fights over content moderation, privacy, recommendation algorithms, and AI are symptoms of one long shift.
Search, social networks and recommendation systems solved real problems of navigation and abundance. Eventually each solution becomes the environment itself, and continues to be optimized for incentives that benefit the companies behind tech solutions. His phrase for how we’ve been reading the news about tech is “paying attention to the weather while overlooking the climate.”
The historical framing will only pay off if later installments name specific mechanisms and the people who made the decisions, and I’m reading the rest to see whether they do. New parts come out twice a week, with a full PDF at the end.
While I still go back to Haraway’s “Situated Knowledges” for the argument that every view comes from somewhere, these days, the writer I read most closely on technology is Dr. Tressie McMillan Cottom.
Haraway asks where a knowledge claim is standing, while Dr. Tressie asks who pays for it. Lower Ed traced how for-profit colleges sold credentials to audiences the rest of higher education had shut out. In a TikTok mini-lecture on AI, politics, and inequality, she carried that analysis forward using Daniel Greene’s “access doctrine,” which holds that the answer to economic inequality is more skills rather than more support, and which universities facing their own precarity have leaned into. Audrey Watters and Ed & Class both wrote it up.
Her question fits my work life better right now while AI begins to show up in procurement, policy and training decks, and her ongoing attention to pedagogy keeps the conversation tied to what happens between a teacher and a student. I read Haraway for the epistemology and Dr. Tressie for the current evidence of how it plays out in real classrooms.
Noted: Because I’m using Gemini to find and complete resources related to the earliest blog years, I’m citing a Clancy throughout my project, which the LLM keeps pulling back to center events and articles related to the Clancy trial.
Neither company publishes a timeline, and most of the numbers floating around come from SEO consultants, so treat this as rough. The short answer is that Gemini usually gets there faster because it searches Google’s index, while Claude appears to search Brave’s, which fills in more slowly.
Gemini grounds its answers in Google Search, so its lag is roughly Google’s indexing lag. That can mean a few days for a page on an established site and two to six weeks for everything else. If your robots.txt blocks Google-Extended, Gemini won’t use your pages for grounding at all.
If you paste a URL directly into either chat, the model reads the page right away without waiting on any index. To check whether you’re findable, search your domain on search.brave.com and in Google Search Console. Blocking ClaudeBot, the training crawler, doesn’t stop Claude from citing you; Claude-SearchBot is the one that governs search.
Fellow SEO/GEO nerds are citing an average of six days to show up in Google’s systems, though it is sometimes taking as long as thirty days on smaller, less-visited sites.
Machines and machine learning change the ways we think about humans and humanity. In cyberspace, we create “digital doubles,” or data doubles, or digital human twins (DHTs), and now these digital doubles move through assemblages of AI systems. New politics are emerging from this tangle.
(I am sad to hear that Soraya passed away last month. During her research for this article, I enjoyed discussing the technical details that created these spaces and how our collective work facilitated everything that came afterward, or didn’t. I know Soraya was hanging a lot of her career on this article and felt it was poorly handled at the time, speculating it was because the voices most implicated by the research now manage the levers of publishing.)
Knowing Google has the juice for search, including all the missing bits deprecated over time, I asked it what technical and social lessons were learned, assuming Gemini could treat that work like a portfolio and provide a business analysis with the full benefits of hindsight.
Per Gemini, links added by me:
Looking back at the mid-2000s, the feminist blogosphere achieved extraordinary cultural breakthroughs, but it also operated with distinct technical and social failings and prejudices. By treating cyberspace as a purely ethereal or detached realm, bloggers unintentionally reproduced offline power dynamics, a phenomenon known as the “digital twinning” of cyberspace.
Viewed through a critical, retrospective lens, four major areas show where different choices around technology, institutional strategy, and social solidarity could have altered digital feminism’s trajectory.
1. Technical: platforms are not neutral
The early blogosphere largely treated technical tools (like WordPress, Blogspot, Google Search, and ad networks) as neutral pipes rather than profit-driven entities with embedded incentives. Bloggers built incredible social capital on free or cheap third-party services without owning the underlying code or digital infrastructure. When Web 2.0 shifted toward algorithmic feeds and centralized social media (Twitter, Facebook), bloggers willingly migrated their engagement to those platforms to chase larger audiences.
Protocol-Level Investment: Instead of relying on proprietary platforms, the cohort could have invested in building and maintaining independent digital commons, including federated software, cooperative hosting collectives and shared digital archives owned directly by the movement.
Data Sovereignty: Early writers rarely anticipated how their essays, comment sections and personal narratives would be scraped, monetized, and eventually used as training data for commercial algorithms and search engines. Establishing strict open-source licensing (such as Copyleft or peer-production licenses) and sovereign archiving practices could have protected intellectual labor from platform extraction.
Many of the highest-profile blogs were anchored by white, college-educated, urban writers who inadvertently treated their lived experiences as the “default” feminist lens. Marginalized writers, particularly Black, Indigenous, AAPI, disabled, and trans writers, frequently had to demand inclusion, fight for citation, or build separate spaces (Racialicious, Crunk Feminist Collective, Reappropriate, FWD/Disabled Feminists) to address the dominant blogs’ weak spots.
Resource and Power Redistribution: Rather than treating traffic and ad revenue as individual metric wins, major sites could have operated as resource-redistribution networks—directly funding, platforming, and sharing domain authority with writers from marginalized backgrounds from the outset. This is what Feministe.us aimed to do with our rotating lineup of guests, with mixed results.
Rethinking “public” vulnerability: The blogosphere heavily rewarded raw, highly personal exposure (“confessional blogging”). However, this cost was asymmetric: white, middle-class bloggers often parlayed personal exposure into book deals, while marginalized bloggers faced severe offline economic risk, doxxing and targeted harassment for sharing the same level of personal detail. Many of us also needed to earn a paycheck with benefits. Depending on your demographics, angles and timing, writing opportunities were limited, and only a small fraction of the talent generated in the collective saw durable career impacts. A more intentional approach would have prioritized pseudonyms, pen names, shared authorship, and safety-first rhetoric.
3. The siren song of individual upward mobility
The most consequential structural shift was how the blogosphere interacted with traditional media and corporate capital. As more corporate outlets (Jezebel, HuffPost, The Guardian) realized feminist commentary drove clicks, they offered individual bloggers lucrative staff jobs, book deals and column spaces. This transformed a collective political movement into a pipeline for individual career advancement. As top talent moved into legacy media, independent blogs lost the labor needed to sustain them.
Building cooperative media outlets: Instead of individual writers accepting staff roles at corporate outlets, the cohort could have formed reader-owned media cooperatives (similar to worker-owned publishing models today). This would have allowed writers to earn a sustainable living while keeping their intellectual output in a community-controlled space.
Resisting algorithmic speed: Legacy media required bloggers to output somewhere between 3-10 quick, hot-take posts per day to satisfy ad-driven impression quotas. Resisting this pressure in favor of slower, deeper, “thick” theory would have preserved the intellectual rigor of the spaces instead of reducing feminism to consumable digital commentary.
4. Politics: Hesitancy to be the “fly in the ointment”
Beyond technical tools and corporate pipelines, there was a profound rhetorical hesitation within many of the era’s flagship blogs to comfortably occupy the role of the “fly in the ointment,” the deliberate, disruptive presence that insists on disrupting false consensus to center genuinely aggrieved interests.
Because major blogs faced constant, bad-faith attacks from right-wing media and anti-feminists, an implicit pressure emerged to project a unified “united front.” This often created an environment where internal dissent, particularly from disabled, working-class, trans, or non-white women pointing out the movement’s ongoing failures, was framed as unhelpful infighting or a distraction from the broader political battle. The push for a polished, accessible and broadly appealing “Feminism 101” frequently smoothed over the jagged edges of critique.
Sanctifying disruption as methodology: The blogosphere could have explicitly framed the “fly in the ointment” not as a threat to solidarity, but as the primary engine of accountability. Rather than managing or policing internal conflict to maintain a clean editorial brand, blogs could have deliberately designed their platforms to hold open space for radical and uncomfortable grievances within the plurality of feminist thought.
Protecting uncommodifiable voices: Corporate platforms favor palatable, easily shareable commentary by design. By shying away from deeply uncomfortable, non-mainstream grievances, the blogosphere left a vacuum filled with endless explainers. A more resilient model would have actively protected and amplified the most uncompromising, “unmarketable” voices, including those whose positions could not be sanitized for an ad sponsor or a cable news segment.
By failing to fully institutionalize the “fly in the ointment” as an essential, protected role within digital spaces, the early blogosphere left itself vulnerable to the corporate absorption that eventually dismantled it. When mainstream media stepped in, it easily plucked away the polished, palatable commentary while abandoning the uncomfortable, dissenting labor that keeps a political movement expansive and honest.
Noted: I’ve been playing with Copilot, Claude and Gemini in tandem, and Copilot and Gemini are suddenly, curiously outperforming Claude by a lot.
Eli Lilly redux: Thinking about the democratization of information and the removal of gatekeepers alongside this story I saw first at Boys’ Club. This Harvard PhD is vibe-manufacturing schizophrenia drugs in his garage. Are we vibe-coding medicine?
Manton on AGI: “As we reach AGI… I’d like to set some ground rules for myself — beliefs that won’t change as technology changes. AI will be smarter than us, but consciousness and ‘a soul’ can’t be created from computation.”
A composition teacher friend shared this paper on social media: Lester Faigley’s “Literacy after the Revolution”, the essay version of his 1996 CCCC Chair’s address. In it, the author argues that the economic impacts of the digital revolution had begun to undo an older commitment, formed in the Civil Rights era, to teaching literacy as a path toward equality. He further argues that writing instruction was being reorganized around tools owned by a few firms (then: Netscape, Microsoft) at a moment when wealth was concentrating upward. Faigley left us with the question of whether educators can hold onto literacy-for-equality while the tides run against it.
Thirty years later, the worry has a new face: AI will do young people’s writing for them and their thinking with it. Ultimately, Faigley believed the need for the skills that composition teaches will keep growing, not despite, but because of our need to convey information in and around that technology and the humanity it serves in a complex society.